Hi 👋

G. Rohith Reddy

Aspiring Data Engineer | CSE–AI Student

Turning raw data into useful answers.

Open to data engineering internships
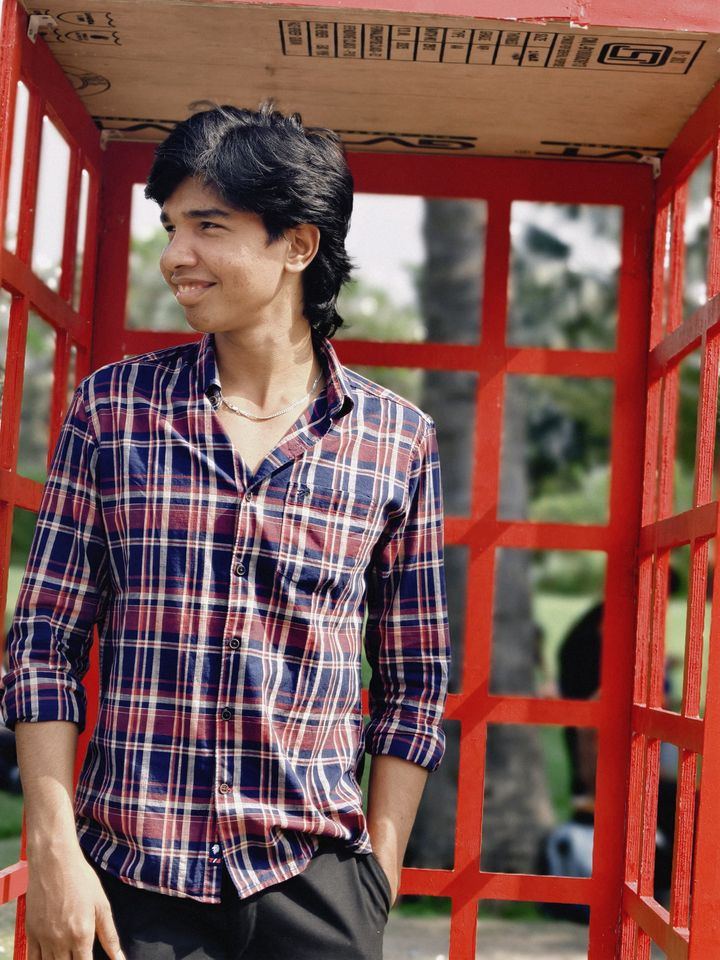
Portrait of G. Rohith Reddy smiling, wearing a checked shirt in front of a red phone booth

I’m a SQL builder

I’m a B.Tech student at Marwadi University focused on the work behind trustworthy data: clear SQL, useful transformations, and pipelines that turn raw information into decisions. I’m building that foundation through hands-on projects, practical certifications, and consistent learning.

3 data projects6 practical certificates4 semesters tracked

The proof

What I bring to the table

I’m G. Rohith Reddy, a B.Tech student in Computer Science and Engineering (Artificial Intelligence) at Marwadi University. My goal is to become a Data Engineer.

I enjoy working with SQL and databases, and I’m building my skills in Python and data engineering through projects on GitHub, practical courses and certificates.

  • 7.25CGPA after 4 semesters (now in 5th)
  • 3Data projects on GitHub
  • 6Certificates from Oracle, Cisco, AWS and CII

How I work

From questions to useful data

01

Start with the question

I break a broad problem into measurable questions first—such as demand, pay, volume, or spending—before writing the query that answers it.

SQL analysis · joins · filters · aggregations

02

Make messy data useful

My ETL project focuses on the practical middle layer: taking raw sales records, cleaning them with Python and pandas, loading them into SQLite, and summarising them with SQL.

Ingestion · transformation · analytical summaries

03

Keep learning in public

I document projects on GitHub and reinforce the fundamentals through coursework and certificates across SQL, cloud foundations, Linux, Java, Python, and applied AI.

Documentation · practice · steady improvement

Selected work
Projects built to make data useful

Featured build · end-to-end warehouse + marts

Data Warehouse & Mart Build: End-to-End ETL Pipeline

Purpose
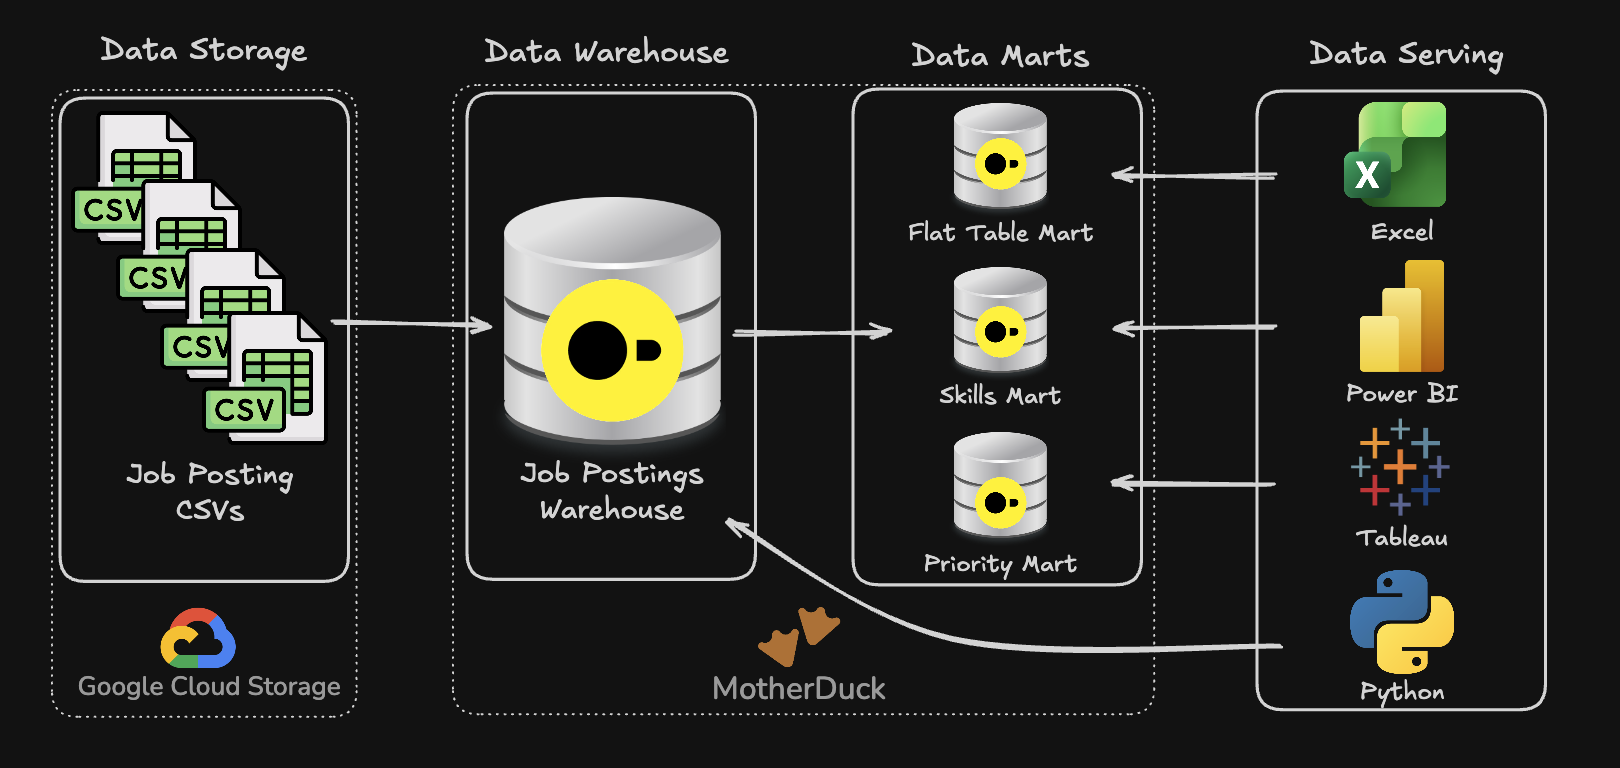
Transform raw job-posting CSVs from Google Cloud Storage into a normalized star-schema warehouse, then create specialized analytical marts for fast, focused questions.
Architecture
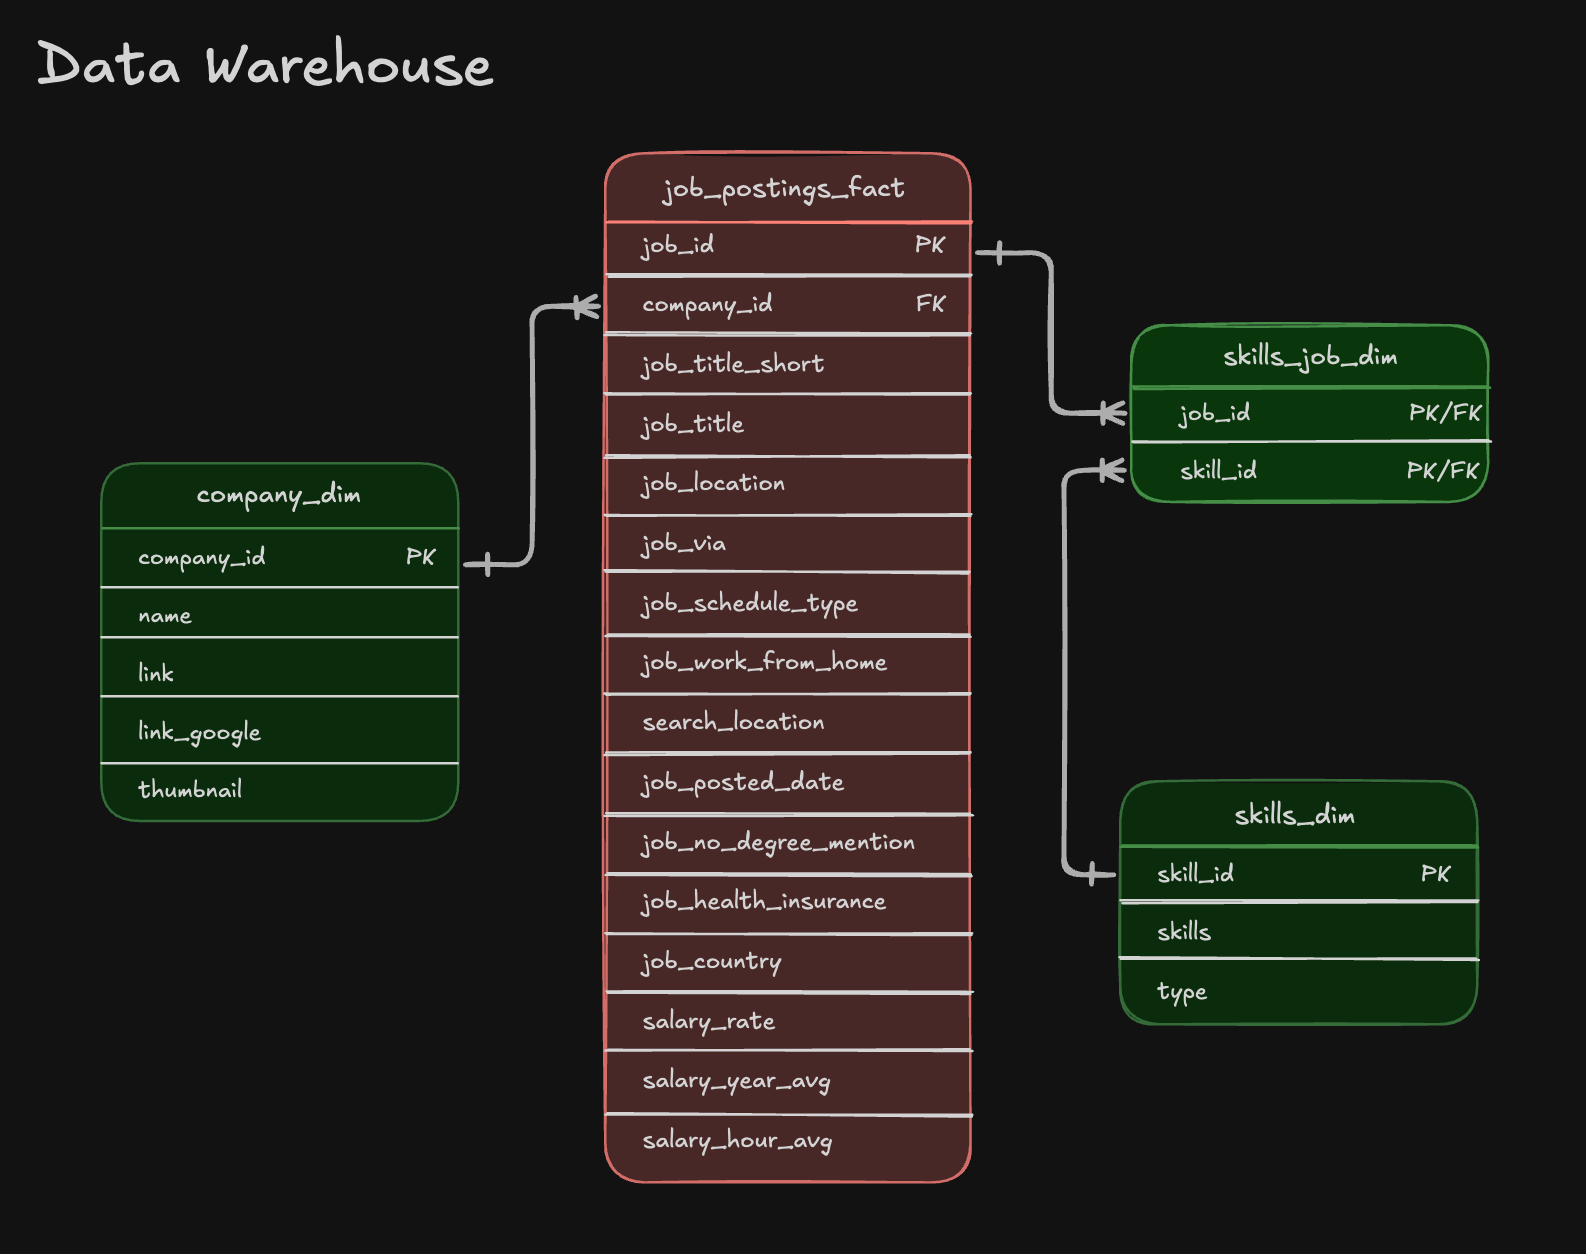
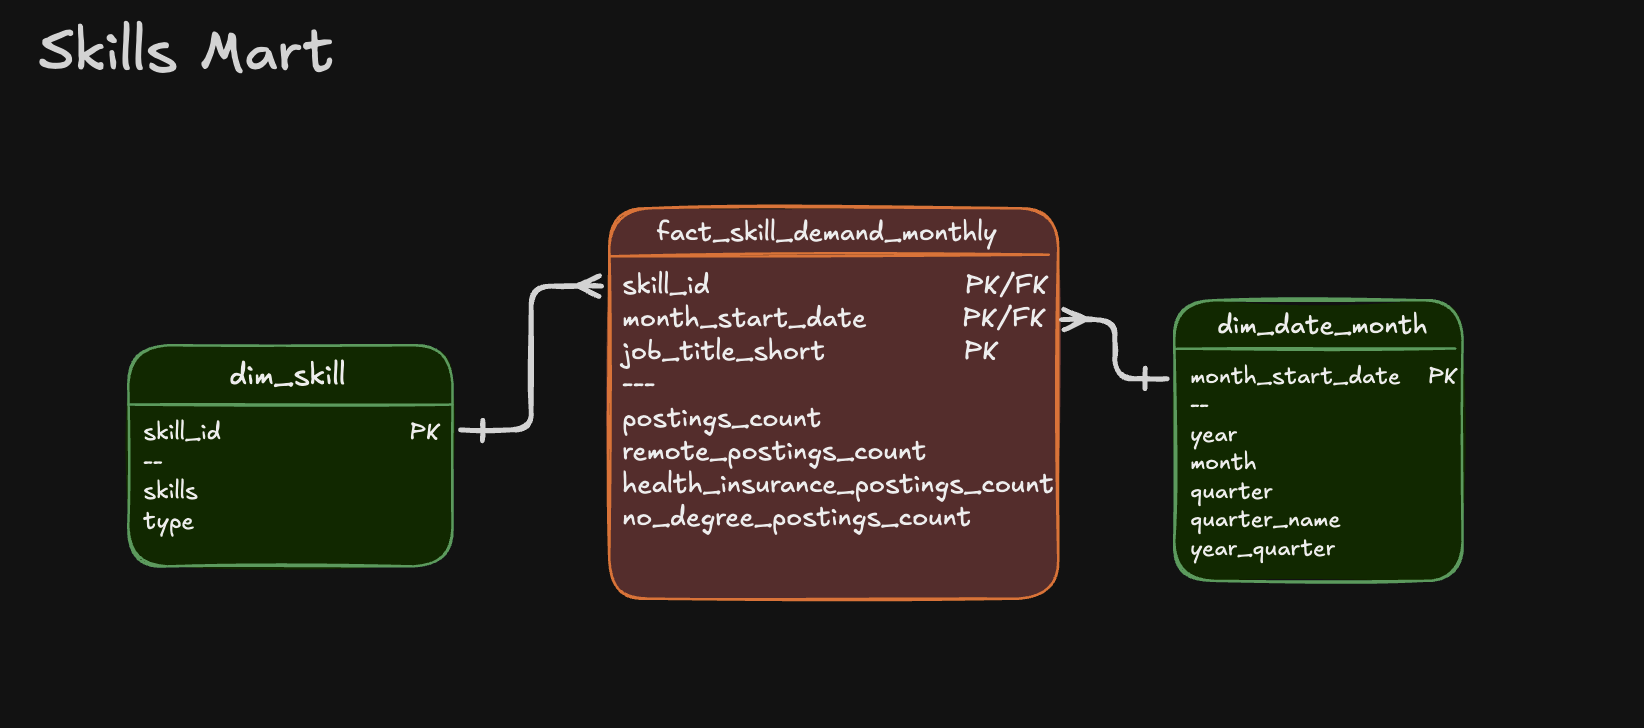
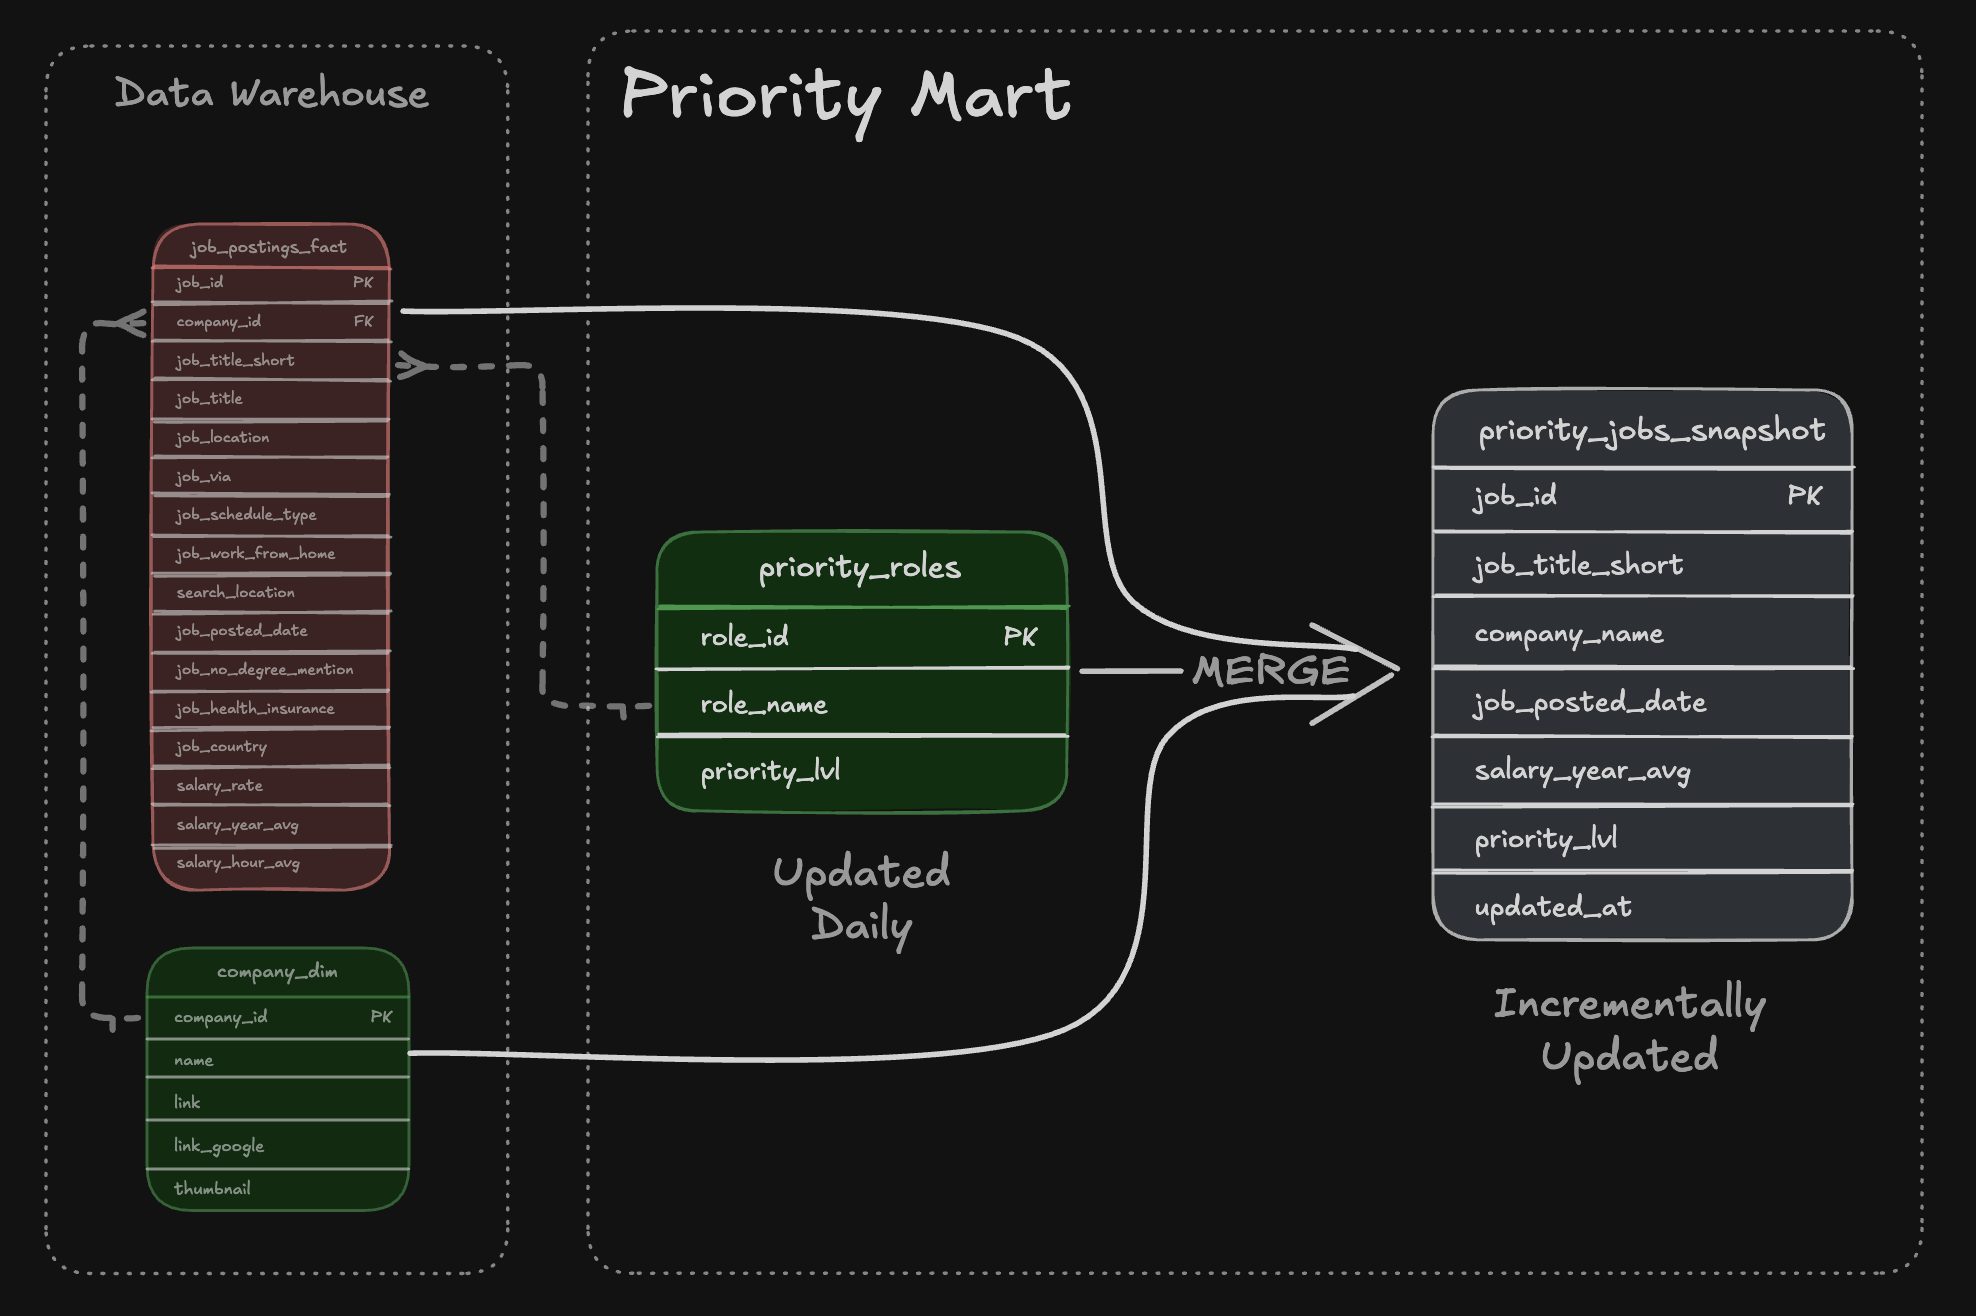
A DuckDB pipeline moves from extraction and loading into company_dim, skills_dim, job_postings_fact and bridge tables, then branches into flat, skills and priority marts.
Technical evidence
Wrote explicit table-creation and loading scripts, defined the grain of the fact table, used explicit data types and record-count checks, and kept reruns safe with DROP TABLE IF EXISTS.
SQL techniques
Uses CTEs, DATE_TRUNC, EXTRACT, STRING_AGG, explicit column mapping and MERGE-based incremental updates for the priority mart.
Tools
DuckDB with httpfs, SQL, Google Cloud Storage, VS Code, Terminal, Git and GitHub
Outcome
A single source of truth for analytical queries plus marts optimized for ad-hoc exploration, skill-demand time series and priority-role tracking.
Data pipeline architecture from Google Cloud Storage through a DuckDB warehouse and analytical marts
01 / PipelineRaw CSVs → warehouse → marts
Star schema data warehouse diagram with fact, dimension and bridge tables
02 / WarehouseStar schema foundation
Skills mart schema for time-series skill demand analysis
03 / Skills martAdditive measures by month
Priority mart schema for role and job snapshot tracking
04 / Priority martIncremental MERGE updates

Data Jobs Analysis (SQL Data Engineering Projects)

Purpose
Explore the Data Engineer job market with SQL: which skills are most in demand, which roles pay the most, and which skills balance salary and demand best.
What I did
Wrote and documented SQL queries on skill demand, median salary and a custom demand-and-pay score for remote Data Engineer postings.
Tools
SQL, DuckDB, Visual Studio Code, Git and GitHub
SQL operations
Joins across multiple tables, COUNT() and MEDIAN() aggregations, and filtering and sorting with WHERE, HAVING and ORDER BY.
Outcome
A documented, reproducible analysis that turns job-market data into practical questions about demand, compensation, and skill choices. In the recorded output, SQL (29,221 postings) and Python (28,776) were the most requested skills.
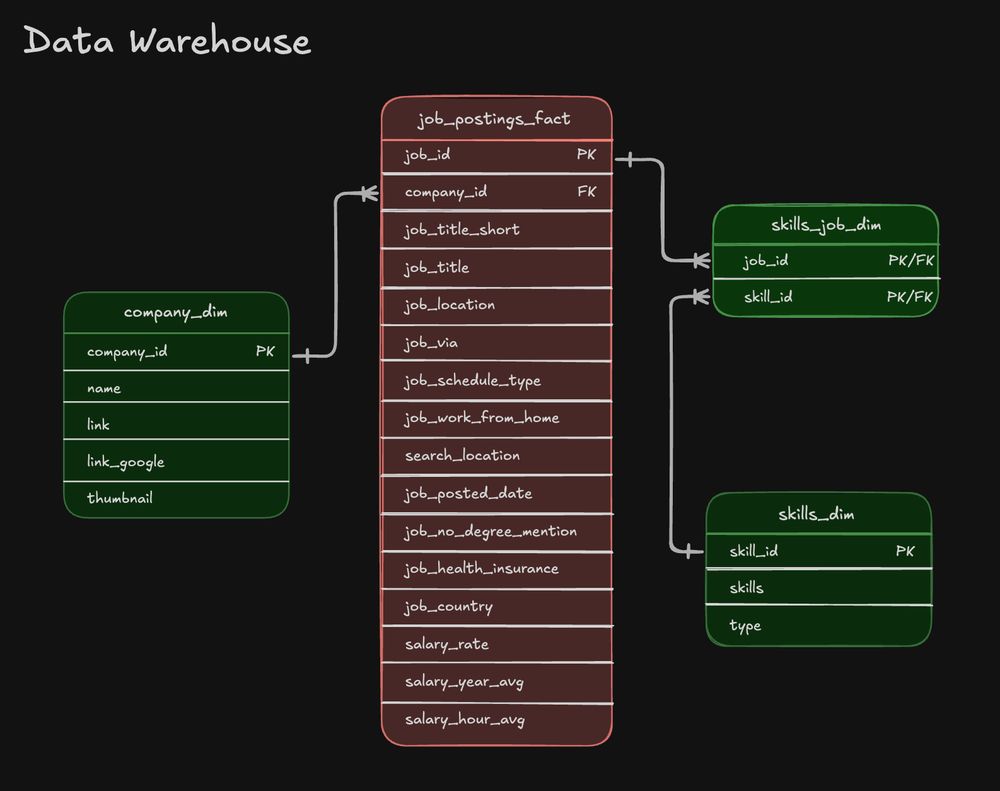
Diagram of the data warehouse tables used in the Data Jobs Analysis project
Data warehouse structure used in the analysis.
Python + SQL · extract, transform, load, analyze

Automated Sales ETL Pipeline

Purpose
Show the complete path from messy input data to a queryable analytical result, in a small project that is easy to check by hand.
Pipeline
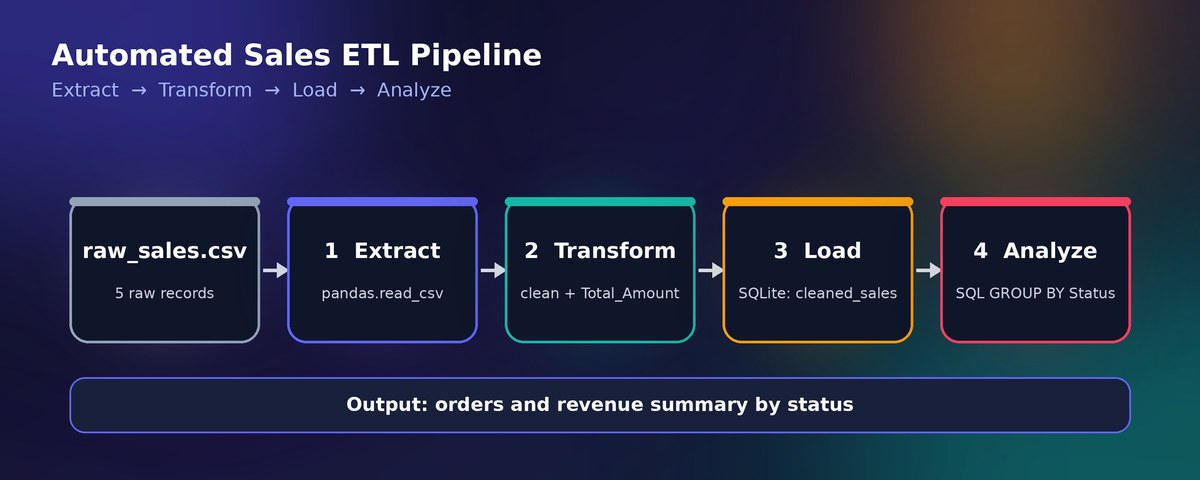
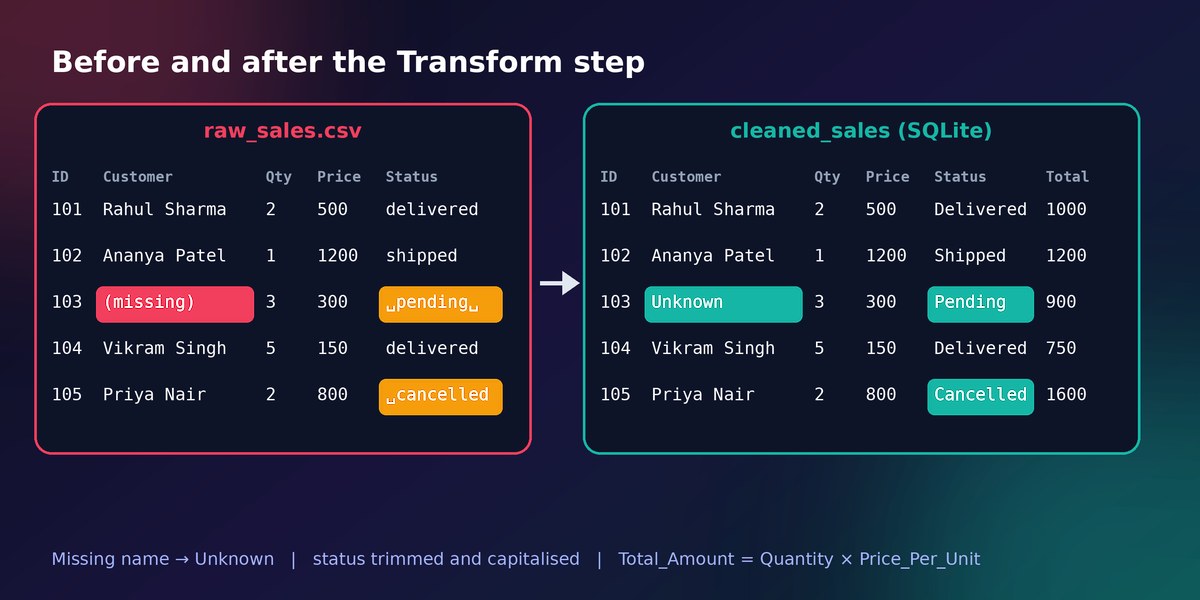
Extract the raw CSV with pandas, Transform it (missing customer names become “Unknown”, order status is trimmed and capitalised, and Total_Amount = Quantity × Price_Per_Unit), Load it into a SQLite table called cleaned_sales, then Analyze with a SQL GROUP BY on status.
Verified output
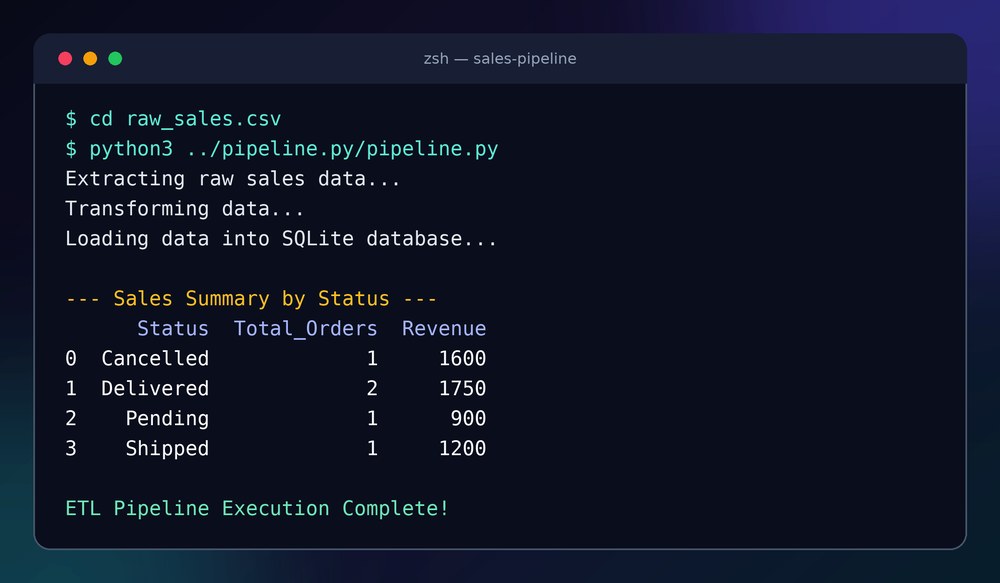
On the sample data it reports 1 cancelled order (1,600), 2 delivered (1,750), 1 pending (900) and 1 shipped (1,200).
Tools
Python, pandas, SQLite, SQL
Scope
A deliberately small build on 5 sample records, made to learn the ETL pattern end to end. Re-running it replaces the table, so results stay reproducible.
Pipeline diagram: raw CSV, extract with pandas, transform, load into SQLite, analyze with SQL GROUP BY
01 / PipelineExtract → Transform → Load → Analyze
Raw sales rows with a missing name and untidy status beside the cleaned SQLite rows
02 / DataBefore and after cleaning
Terminal showing the pipeline run and the sales summary by status
03 / OutputReal run on the sample data

Skills

Technical skills

Programming

  • Java working knowledge
  • C working knowledge
  • C++ working knowledge
  • Python (pandas) learning

Databases and data

  • SQL practising
  • DuckDB practising

Data engineering

  • ETL pipelines learning
  • Star-schema warehouse practising
  • Data cleaning and transformation practising
  • Analytical data marts practising

Tools

  • Git and GitHub using
  • Visual Studio Code using

Basics

  • Linux basics
  • AWS cloud basics
  • Machine learning basics

Education

Education

  • B.Tech, CSE (Artificial Intelligence)

    Marwadi University, Rajkot · 2024 – 2028 (expected)

    CGPA 7.25 after 4 semesters · currently in 5th semester

  • Intermediate (Class XII)

    Vamsi Junior College, Srikalahasti · 2024 · 80.9%

  • Secondary School (Class X)

    Bhashyam High School, Srikalahasti · 2022 · 86.8%

Relevant coursework: Database Management Systems, Data Structures, Programming with Python, Java Programming, Machine Learning Essentials, Operating System and Virtualization, Probability and Statistics.

B.Tech SGPA by semester

Sem 1Sem 2Sem 3Sem 4

Credentials

Proof of consistent learning

Select a certificate to view it.

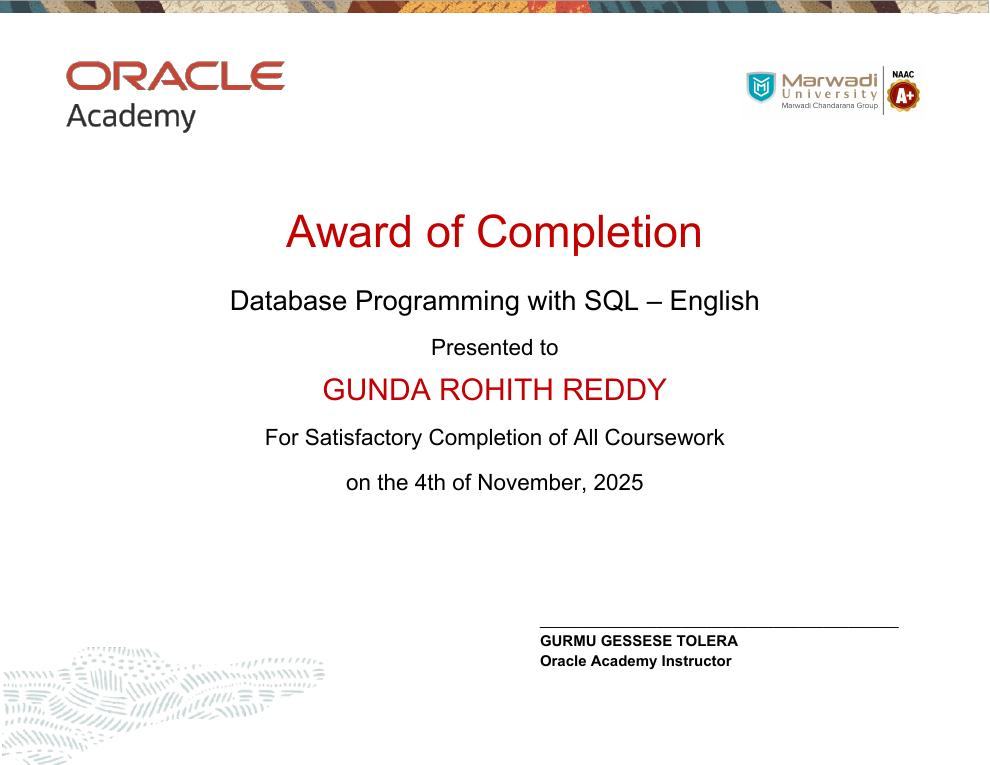
Database Programming with SQLOracle Academy · Nov 2025Certificate: Database Programming with SQL, Oracle Academy · Nov 2025
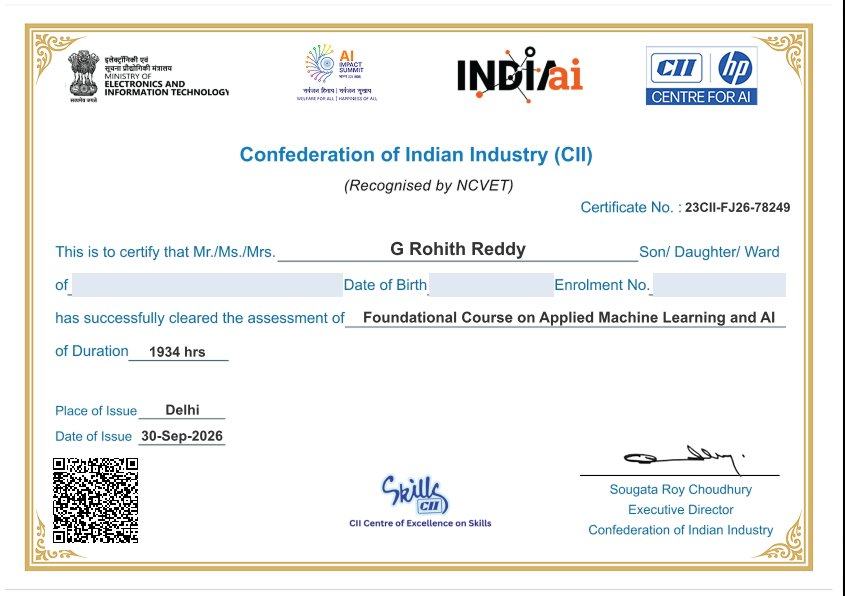
Applied Machine Learning and AI (Foundational Course)Confederation of Indian Industry (CII) · Sep 2026Certificate: Applied Machine Learning and AI (Foundational Course), Confederation of Indian Industry (CII) · Sep 2026
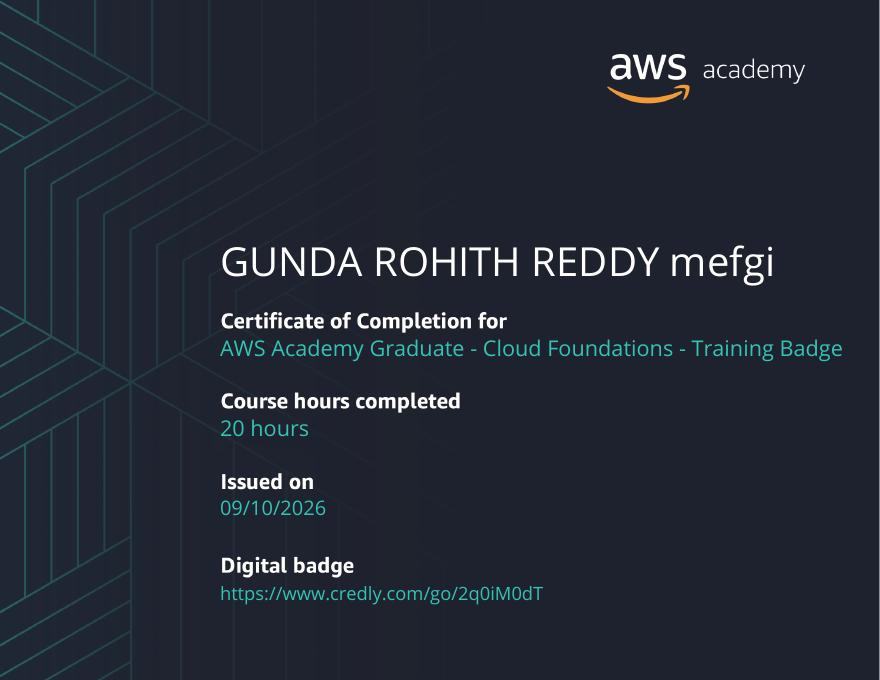
AWS Academy Graduate: Cloud Foundations (20 hours)AWS Academy · 2026Certificate: AWS Academy Graduate: Cloud Foundations (20 hours), AWS Academy · 2026
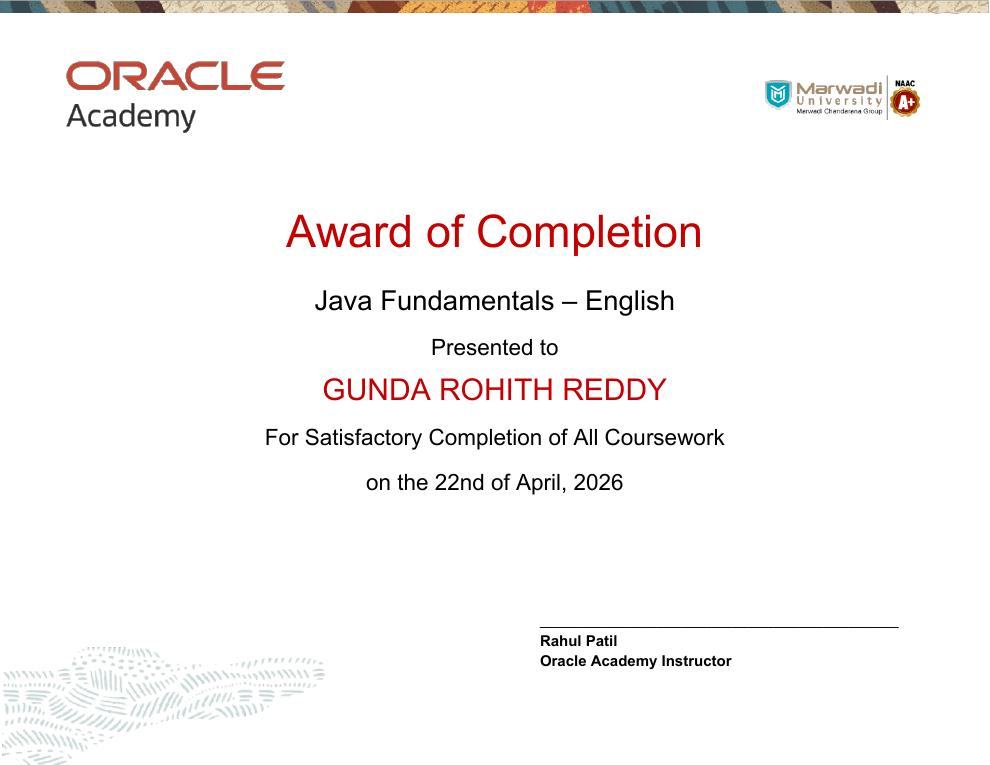
Java FundamentalsOracle Academy · Apr 2026Certificate: Java Fundamentals, Oracle Academy · Apr 2026
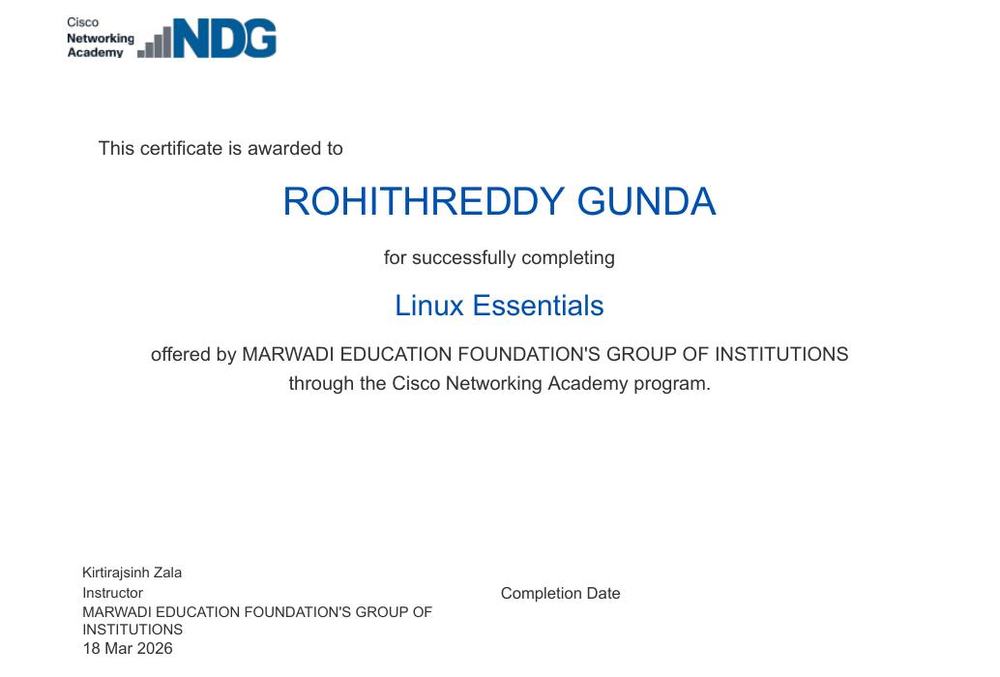
Linux EssentialsCisco Networking Academy · Mar 2026Certificate: Linux Essentials, Cisco Networking Academy · Mar 2026
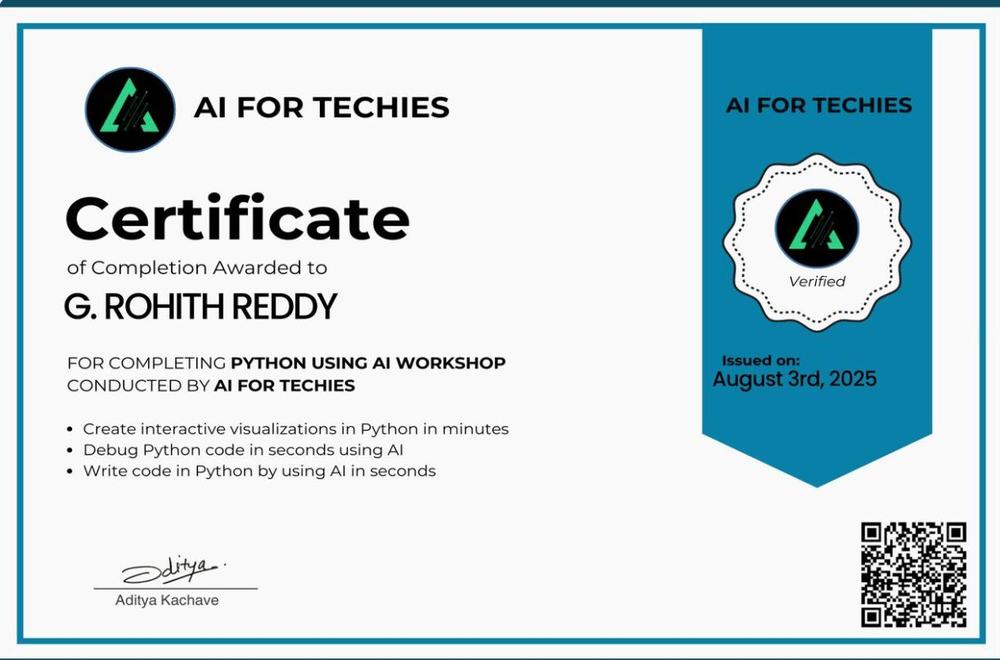
Python using AI WorkshopAI for Techies · Aug 2025Certificate: Python using AI Workshop, AI for Techies · Aug 2025

Achievements

Achievements and interests

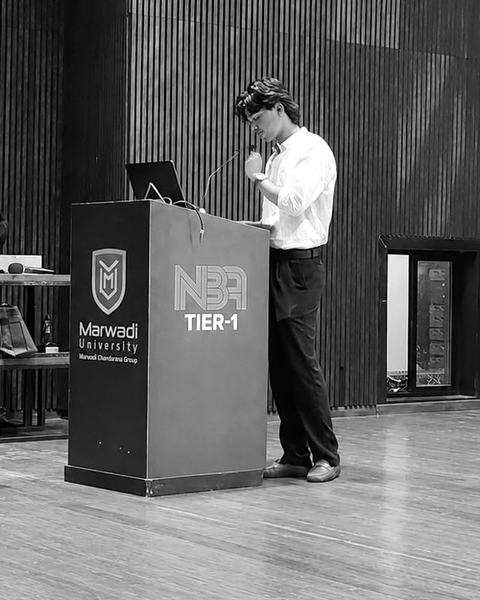
G. Rohith Reddy speaking at a podium on stage at Marwadi University

Hosted the expert session “RAG from Scratch”

Hosted an expert session at Marwadi University in October 2026 featuring Ms Abhilasha Mangal, Senior Data Scientist at IBM, with 1,500 students attending. I supported event coordination and technical communication, which strengthened my presentation skills and my ability to hold an audience’s attention.

Interests: music and old-school gym training.

Next step

Let’s build something useful

I’m open to internship and entry-level data engineering opportunities where I can contribute with SQL, learn from experienced engineers, and keep turning messy data into clear outputs. The best way to reach me is by email.

gundarohithreddy@gmail.com